
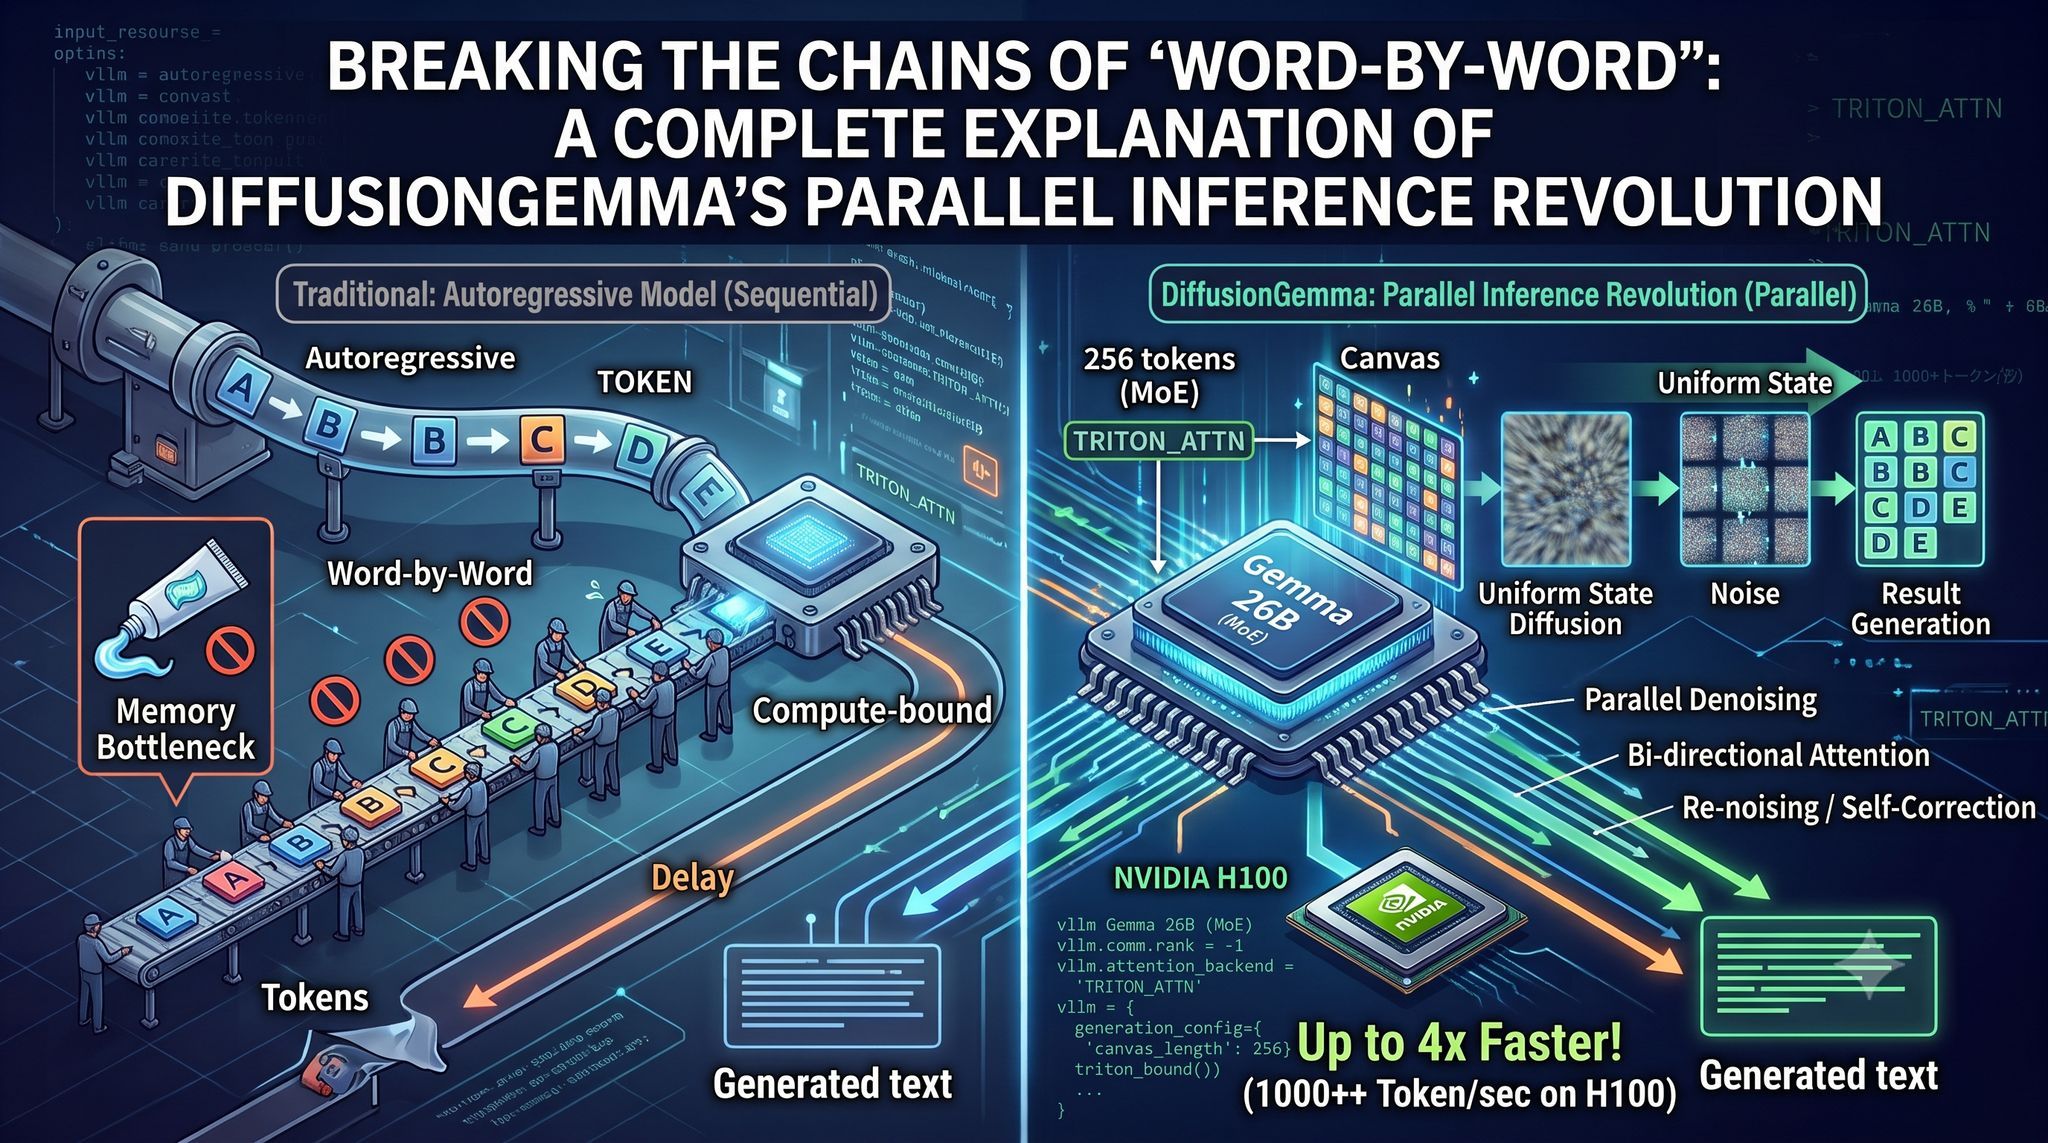
Decoding DiffusionGemma: A Parallel Inference Revolution Beyond Autoregression
This post explores DiffusionGemma, a novel approach designed to overcome the "word-by-word" bottlenecks of traditional autoregressive models. By utilizing "Uniform State Diffusion," the model generates and refines 256 tokens in parallel, shifting constraints from memory bandwidth to compute to achieve up to 4x faster inference. It features bidirectional attention for global context and re-noising capabilities for self-correction. Ready for deployment via vLLM, DiffusionGemma represents a significant advancement in maximizing LLM inference efficiency.