
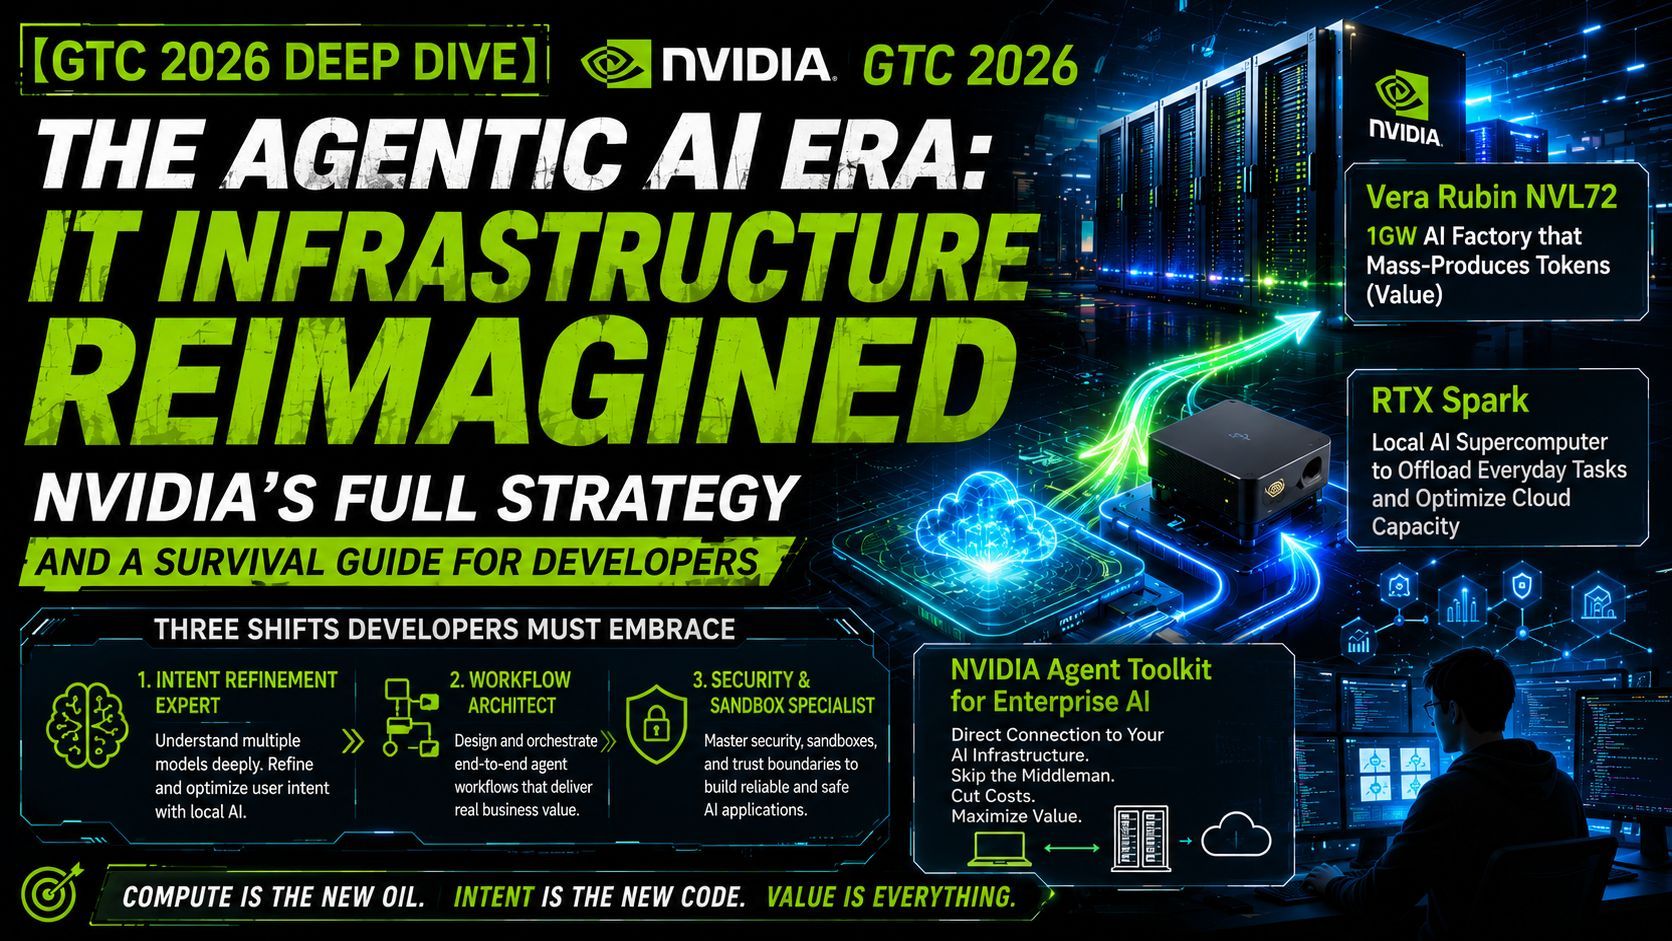
[In-Depth Analysis of GTC 2026] Restructuring IT Architecture in the Age of Agentic AI: NVIDIA's Full Strategy and a Programmer's Survival Guide
This article delivers a deep dive into the NVIDIA GTC 2026 keynote, explaining how the evolution of AI is transitioning from mere "conversation" to "autonomous action (Agentic AI)." From an engineer's perspective, it details how hardware (Vera CPU, RTX Spark) is being redefined and how traditional cloud-centric IT structures are being restructured through local edge processing and NVIDIA's proprietary ecosystem. It also comprehensively covers the essential workflow development skills and low-level architecture knowledge that future developers must acquire.

First, the Introduction: NVIDIA GTC 2026 Keynote Highlights Summary
At the GTC Taipei 2026 keynote, NVIDIA CEO Jensen Huang proudly declared, "AI has now gone far beyond the realm of chatbots. The era of 'Agentic AI' (autonomous AI agents) has officially arrived."
This article is not just another bulleted list of trending news. From an engineer's perspective, we will dive deep into the underlying technical context and the story behind it. Let’s unpack "Why is NVIDIA going all-in on Agentic AI right now?" and "How did they redefine hardware—specifically the Vera CPU and Vera Rubin—to achieve this?"
1. What is the Pain Point of Existing AI? —— The Explosion of "Useful AI"
The generative AI boom of the past few years certainly triggered a revolution, but the interaction remained confined to a single back-and-forth: "a human inputs a prompt, and the AI outputs text." However, Jensen Huang noted that with the arrival of Agentic AI, true "Useful AI is finally within our reach."
An agent is not just a Large Language Model (LLM). It is a "completely new computing model" made up of the following components:
- The Model (The Brain): Responsible for reasoning and planning.
- Security Suite / Console (The Body and System): Manages short-term (working) memory and long-term memory, orchestrating the entire process.
- Tools and Skills (The Equipment): Autonomously operates spreadsheets, browsers, databases, and even NVIDIA’s CUDA-X libraries.
"The narrative that 'AI will steal human jobs' is complete nonsense. In fact, the opposite is true—AI is giving enterprises every reason to hire *more* software engineers."
Astonishingly, the number of developer commits on GitHub exploded from 300 million in 2023 to nearly triple that by early 2026. Engineers worldwide, who collectively earn roughly $3 trillion in salaries, have received such a massive buff from Agentic AI that they are now generating up to $9 trillion in productivity value.
From a developer's standpoint, this marks the dawn of a new era where AI handles not just "automated coding," but the "autonomous building and validation of entire systems." In fact, NVIDIA has already partnered with Cadence to build a super-agent that slashes the RTL (Register-Transfer Level) verification cycle in chip design from "weeks to mere hours."
2. Agents are All "Impatient" —— The Logic Behind the Birth of the Vera CPU
You might be wondering, "I get that Agentic AI is incredible, but what changes does this bring to the hardware side?" This is where NVIDIA truly shines.
Traditional CPUs were designed "for humans." Because humans live in a world measured in seconds, the most efficient approach was to slice threads and cores in the cloud and rent them out by the slice of time. However, AI agents are incredibly impatient.
When an agent calls a tool or accesses a database, even nanosecond-level latency becomes a bottleneck. To shatter this bottleneck, NVIDIA built the Vera CPU from scratch, customized purely for agents.
💡 Tech Perspective: What makes the Vera CPU so compelling?
- Pushing Single-Thread Performance to the Absolute Limit: To process massive throughput alongside heavy Python runtimes and tool calls at lightning speed, NVIDIA pushed the IPC (Instructions Per Cycle) to an astonishing 10.
- Massive Memory Bandwidth: Utilizing LPDDR5X, peak memory latency was cut by 40% compared to x86 architecture. Furthermore, by eliminating the overhead associated with chiplet boundaries (the chiplet tax), they beautifully unified 88 Olympus cores via a single 3.6 TB/s Monolithic Mesh Fabric.
- A Streaming Processing Monster: In real-time streaming processing tests simulating the New York Stock Exchange, it delivered a mind-blowing 6x performance increase over existing CPUs.
Agentic AI is essentially a decentralized computing model. Inference happens on the GPU (Vera Rubin), while tool calling and memory management (KV cache) are handled by the CPU. This requires ultra-tight coordination between the two. The Vera CPU is a wolf in sheep's clothing—a spec monster born to completely obliterate the "agent bottleneck."
3. RTX Spark —— The First "Reinvention of the Personal Computer" in 40 Years
Of all the announcements, the evolution on the client (edge) side is perhaps the most exhilarating.
Jensen Huang declared, "Microsoft and NVIDIA have completely reinvented the PC." The core of this revolution is the next-generation PC powered by the new RTX Spark chip.
- Specifications: Co-developed with MediaTek, this custom chip (N1X) packs 6,144 CUDA cores, a 20-core Grace CPU, and 128GB of unified memory. Its AI computing performance reaches an earth-shattering 1 PFLOPS.
- Resident Local Agents: Users no longer need to worry about metered cloud costs or bandwidth caps. Agents can now run efficiently 24/7 directly in the local environment.
🛠️ How This Flips the Industry on Its Head
Right now, our daily digital life consists of a continuous loop of "opening apps, clicking, and typing." In an RTX Spark environment, however, an agent resides inside a security sandbox called "Open Shell." From there, it can directly operate local CAD software (like Rhino) to design a house for you, or automatically spin up Blender to handle rendering on its own.
The future PC is no longer just a tool; it transforms into a personal AI assistant—akin to housing R2-D2 or C-3PO right inside your desktop chassis.
4. The Forefront of Open-Source Models and "Physical AI"
For software and robotics engineers, the reinforcement of the open-source ecosystem is another major highlight.
- Neotron 3 Ultra: A brand-new open-source model utilizing a hybrid architecture that combines SSM (State Space Models) and MoE (Mixture of Experts). This allows it to run 5x faster while cutting costs by 30% compared to models in its class. In a remarkably generous move, NVIDIA released not just the model, but the entire training scripts and datasets.
- Cosmos 3: A World Foundation Model that understands not just language, but the laws of physics. It goes beyond generating videos and images to serve as the foundation for "Physical AI," enabling robots to plan actions and run simulations.
- NVIDIA Isaac Groot: An open-source reference platform for humanoid robots. Jensen playfully quipped, "It stands 6 feet tall and weighs 150 pounds—roughly the same as me (though the first number is a bit smaller than me, and the second is a bit larger)." This playful yet powerful robotics platform is set to become a vital milestone for future robotics research.
Deep Dive & Analysis NVIDIA GTC 2026: Restructuring the IT Order Through Agentic AI — Dissecting the "Jensen Strategy"
Foreword: *From here on out, this section includes the author’s personal deep-dive and technical interpretation. Please enjoy it as a perspective on the industry.*
Throughout the keynote, Jensen Huang remained elegant on stage, expressing gratitude to the Taiwanese supply chain and praising the beauty of mathematics. However, beneath that warm corporate facade lies a fiercely rational business strategy. He skipped the hollow promises and went straight for the jugular, targeting the profit distribution structure and technical paradigm shifts of the IT industry. Looking at this, the path forward for developers became crystal clear.
GTC 2026 in Taipei kicked off amidst historic cheers, backed by a staggering 10% projected GDP growth rate for Taiwan.
Most people are still looking at this as an festival of specs, marveling at "3nm processes," "HBM4 memory," and "multi-trillion parameter supercomputers the size of skyscrapers." But if you carefully review the entire keynote, the message Jensen sent to the world was incredibly direct and struck at the very core of business logic.
To put it in plain English: "Skip the lectures. Our goal is singular — to generate massive economic value!"
To lead all clients toward achieving an overwhelming Return on Investment (ROI), he executed a lightning-fast, earth-shaking triple strategy during this keynote.
I. Full Mass Production of Vera Rubin: A Custom "Digital Value Engine" for Top Enterprises
For executives and enterprise leaders who can invest massive capital but don't necessarily have the time to dissect the inner workings of deep learning, Jensen has laid down a seamless track.
There is no need to spend time studying the minutiae of Transformers or SSMs at a granular level. Jensen’s solution is the answer: "Don't waste time overthinking it. Invest, and buy the NVIDIA DSX AI Factory solution lock, stock, and barrel!"
The NVIDIA DSX Blueprint ──> Digital Twin Factory Simulation in Omniverse ──> One-Click Launch of Physical Factories ──> Continuous Creation of Tokens (Value)
Jensen laid out the math clearly on stage: "Computing power is revenue, and power consumption is profit."
In a world teetering on a 1GW (Gigawatt) power limit wall, using cheap, inefficient chips is a massive opportunity cost. NVIDIA packages everything—the chips (Vera Rubin NVL72), racks, cooling systems, power supplies, and networking (CPO: Co-Packaged Optics)—into a flawless, tightly integrated machine. Once the system is spun up, it produces "tokens" at an overwhelming speed.
In the Agent era of 2026, every single token translates directly into business productivity. Jensen’s execution and NVIDIA's dominant ecosystem serve as the ultimate guarantee.
"The more you buy, the more you save. The more you invest, the greater the returns!" This is not marketing hyperbole. This is about real physical constraints and the extreme edge of engineering yielding massive premium value.
II. Flipping the Table! Jensen’s Restructuring of the Entire IT Hierarchy
If the first point was an invitation for enterprise investment, the second point is Jensen’s total audit and restructuring of the entire IT ecosystem.
2.1 Optimizing the Edge: Stop Wasting Precious Cloud Compute on Casual Queries!
As a fellow engineer, looking at how casual users interact with AI recently made me realize something: it is incredibly wasteful from a resource perspective to burn precious cloud computing power—built on the sweat, blood, and silicon wafers of top engineers—on trivial Web-prompt queries.
- "What historical figures share my last name?"
- "Can you write a quick pun for me?"
- "Can you draft a venting essay about a family grievance?"
Until now, because tech giants were in the phase of "driving AI adoption" and "habit formation," they had to grit their teeth and absorb this resource waste. They watched high-end computing power, built at astronomical costs, get eaten up by free, casual queries, leaving cloud platforms struggling to allocate enough bandwidth for high-margin enterprise monetization.
In 2026, to optimize this resource imbalance, a move has been made!
NVIDIA teamed up with ARM and Microsoft to unleash the ultimate weapon for the edge: NVIDIA RTX Spark!
【NVIDIA RTX Spark】 = 20-core Grace CPU + Blackwell GPU (6,144 CUDA cores) + 128GB Unified Memory
- Low-level integration with Microsoft's Windows Agent OS + Locally running Neotron 3 flagship model
This is a monster local chip boasting 1 Petaflop of AI compute and 70 billion transistors. The strategy behind it is masterful:
- Decentralizing Compute (Lightening the Cloud Load): By purchasing an RTX Spark-powered PC, users can run 2024 GPT-class models locally with zero network connection, zero latency, and zero data costs. It also comes with the built-in Hermes Agent and Open Shell agent sandbox. Casual banter, local file searches, image editing, and basic code execution can all be handled right on the user's local machine using local power. This frees up the goldmine that is the "AI Factory" (the cloud computing platform) to focus entirely on ultra-high-value enterprise agent operations in finance, healthcare, and heavy industry.
- Redefining the Developer Ecosystem: Giving the client side such terrifying local compute completely rewrites the rules of IT development (detailed in Section III).
- Capturing the Local AI Market Share: Over the past few years, Apple carved out a unique position in the lightweight local AI space with its Mac Mini and M-series chips, posing a notable trend in the consumer GPU market. The birth of RTX Spark rallies the Windows camp to deliver a powerful counter-strike, reshaping market share on the edge.
2.2 Reducing "Mega-Cloud" Intermediary Costs: NVIDIA Agent Toolkit for Enterprise AI
This move will undoubtedly pose the most significant challenge to the traditional business models of the Big Three cloud providers (AWS, GCP, Azure).
Previously, when an enterprise wanted to develop an AI service, they had to take a tortuous route:
Client Data -> Connect to AWS/GCP/Azure Platform -> Hit Cloud APIs -> Route to Backend NVIDIA GPU Clusters -> Return along the same path
From an infrastructure optimization standpoint, this means paying for an incredibly round-about architecture. Why should a complex intermediary layer sit between NVIDIA's GPUs and the user's terminal, tacking on massive "server management fees and bandwidth costs"?
With this announcement, Jensen directly pulled out the NVIDIA Agent Toolkit for Enterprise AI!
【The Direct Path of the AI Era】 RTX Spark (Client Terminal) ──(Direct Connection)──> Enterprise Private/Hosted NVIDIA AI Compute Infrastructure (DSXOS) ▲ [Skips traditional third-party cloud data relaying and high management costs]
NVIDIA is directly providing a development framework that plugs straight into the lowest layer of infrastructure. Enterprises investing in NVIDIA infrastructure will no longer need to rely excessively on complex, expensive traditional cloud vendor management platforms, saving massive overhead. It allows the local RTX Spark terminals mentioned in section 2.1 to plug directly into the baseline AI compute factories.
This macro strategy leverages pure technology and ecosystem synergy to ensure that every dollar invested is sharpened into a weapon for generating returns. Jensen’s strategy leaves no room for inefficiency.
III. The Transformation Has Begun: How Will IT Programmers Survive?
Under this grand blueprint of "Agentization" and "Compute Optimization," traditional IT development models will be forced to undergo a massive evolution.
3.1 A Cold Restructuring of the Rules of the Game
In the future, large enterprises will adopt NVIDIA infrastructure to build proprietary "Agent AI Services"—a completely self-contained, novel form of service.
Corporations cannot afford to let the computing power they secured at a premium be inefficiently drained by outside forces. Consequently, raw interfaces like traditional APIs and MCPs, which allow direct programming access, will increasingly be locked down or restricted due to security and cost controls.
Instead, low-level code will be absolutely isolated. They will utilize tools like VibeCoding (ultra-abstracted tools where code is written based on high-level intent) to lock core code entirely inside sandboxes, shielding it completely from anyone outside the NVIDIA ecosystem.
What enterprises expose to the outside world will only be upgraded versions of "Skills," or highly abstracted interaction protocols existing as "AI CLIs" (Agent Command Line Standards).
3.2 The Paradigm Shift for Client Developers: Moving to "Workflow Development" and "Intent Refining"
The job of a client-side programmer will no longer be about "sincerely writing code just to hit an API." Your core responsibility will shift entirely to Workflow Development.
Imagine a user inputs a highly ambiguous, scattered "intent" (what they want to achieve) in a local environment.
You must not feed this low-resolution intent directly into an expensive, enterprise-grade cloud agent. Doing so would simply flush server costs down the drain.
Instead, you must leverage the Local Model running on the local RTX Spark alongside the Harness framework to conduct step-by-step guidance, error correction, sandbox rehearsals, and intent completion right on the edge.
And then, the moment the information density and accuracy of that intent cross the "invocation threshold" defined by the enterprise agent service, you trigger the high-cost, but guaranteed-accurate cloud agent.
【The Execution Logic of Future Software】 [User's Ambiguous Intent Input] │ ▼ [Local RTX Spark (Local LLM + Harness)] ── Guided deep-dive, auto-completion, sandbox validation │ ▼ (Intent Information Threshold Reached) [Cloud NVIDIA Agent Factory] ── Executes high-value, high-precision invocation, outputting perfect results instantly
IV. There is No Time to Wait. What Should We Learn and How Do We Prepare?
This sci-fi-like era isn’t 10 years away. With the mass production of Vera Rubin and the launch of RTX Spark, it is already knocking on our door. To avoid being left behind, developers must pivot their tracks immediately.
To expand your knowledge base and meet these new challenges, I highly recommend adopting the "XY-Axis Step-Up Learning Method." https://www.vibecodingjapan.com/blog/1779634570095?lang=en
1. Become a "Multi-Model Intent Refining Expert" Y-Axis: Technical Depth & Model Characteristics
Stop relying solely on a single closed model like GPT and hitting a wall when it changes.
You need to understand the physical characteristics of various LLMs down to their bones—especially the performance limits of the upcoming local small models and hybrid SSM (State Space Model) architectures.
The mechanism you need to design looks like this: Evaluate user intent -> Route the task to the most cost-effective local small model -> Use the small model to ask the user clarifying questions and fill in context -> Validate the intent description locally -> Meet execution standards.
The skill to design this type of "intent interpretation enhancer" will become a powerful asset for your future career.
2. Keep a Close Eye on All "Harness Frameworks" X-Axis: Ecosystem Breadth & System Architecture
"Harness Frameworks" are the Spring Boot and Django of the AI era. Whoever can orchestrate LLMs locally the fastest and most accurately, schedule memory (KV cache compression tech), and invoke security sandboxes will win the game. Elite developers are already studying low-level evolutions like Harness Engineering. The moment a highly efficient new Harness framework hits the industry, they jump on it, master it, and build a technical moat around their skills.
3. Cultivate "Human Judgment" and "Business Deconstruction" Beyond the Machine The Area Formed by the XY-Axes
AI can generate 10,000 lines of code via VibeCoding, but it cannot guarantee whether that code will actually generate profit or value in a real-world business scenario.
Use the XY-Axis Learning Method to rapidly expand your business boundaries. Understand finance, understand the supply chain, understand hardware, and understand the true, often ambiguous desires of human beings. Define "what AI should solve" through your cognitive framework, and maximize your ultimate control over "what AI can do" through the sheer breadth of your XY-axes. (In other words, this is precisely the talent most in demand right now: the FDE or Forward Deployment Engineer!) https://www.vibecodingjapan.com/blog/1779372102828?lang=en
Conclusion
At GTC 2026 in Taipei, Jensen Huang, with his signature smile and near-miraculous engineering execution (slashing rack assembly from two hours down to five minutes, mass-producing Vera Rubin), told the world:
"The factories of silicon intelligence are already running at full capacity across all lines. There is no conductor on this train of time. Only those who jump aboard first will claim the initial dividends of the Token Era."
This is a brand-new game for courageous challengers. Developers, let go of your attachment to legacy code. Armed with your local RTX Spark, let us march forward to meet the bright tomorrow shaped by workflows and agents!